Criteria to Decide Algorithm
Describes the criteria to decide which algorithm is better to use.
Pros and Cons of Each Algorithm
For the algorithm based on automata theory, there are the following pros and cons.
Pros:
- Detection is fast because no actual matching is done.
- Theoretically, accurate detection is possible.
Cons:
- Depending on the regular expression, the size of the equivalent finite state automaton may explode, making detection very slow.
- Not all practical regular expressions can be handled.
On the other hand, for the fuzzing algorithm, there are the following pros and cons.
Pros:
- It can handle all practical regular expressions.
- It is possible to determine vulnerable regular expressions from a practical point of view, as opposed to a theoretical one.
Cons:
- It is possible to erroneously detect a vulnerable regular expression as safe.
- Detection takes some time because the actual matching is done.
Based on these pros and cons, we will consider the criteria for deciding an appropriate algorithm for a given regular expression.
Criteria
If it is likely to be detected correctly by the algorithm based on automata theory, we should use that, otherwise, or if detection is impossible, we should use the fuzzing algorithm.
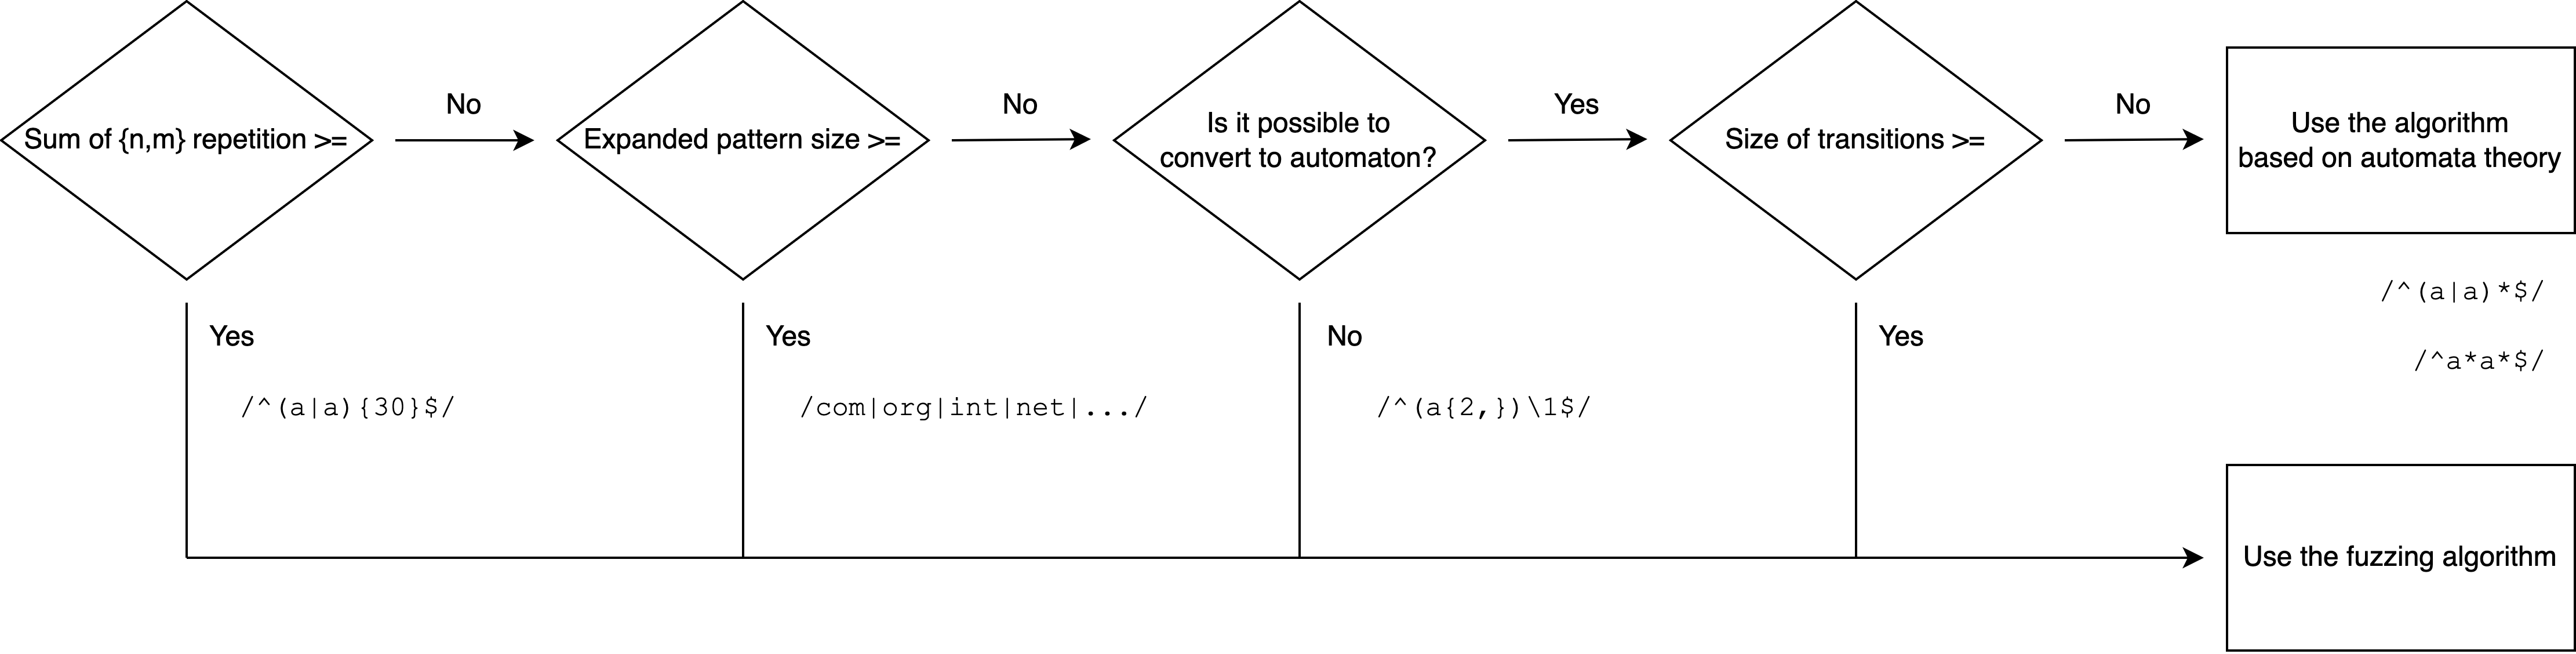
In practice, as shown in the following flowchart, the algorithm is assumed to be based on automata theory at first and performs NFA conversion, etc., and then falls back to the fuzzing if the size of the NFA, or of the DFA built from it, exceeds the threshold.
The algorithm based on automata theory models a back-reference exactly when the groups it refers to match at most maxBackReferenceStrings strings together (e.g. ("|') in /("|').*?\1/): the states of the automaton record what the groups captured, and the back-reference reads it.
It gives up on the other back-references and the constructs that it cannot model exactly.
Then the fuzzing first builds an automaton that explores every path the backtracking may take: a look-around may or may not succeed, and a back-reference matches one of the strings that the groups it refers to may match, or the empty string.
The matching time of this automaton bounds the one of the regular expression from above.
If the bound is linear, the regular expression is safe without fuzzing (e.g. /^([a-z]+)=\1$/).
Otherwise, the fuzzing starts from the attack strings of the bound (see Seeding).
The repetitions of the largest counts become * or + in the bound until the sum of the rest is below the threshold of the repeat counts (e.g. /^[a-z]{1,64}@[a-z]{1,255}$/ is safe, as the bound of /^[a-z]+@[a-z]+$/ is linear).
As the bound is a part of the fuzzing, the fuzz checker bounds a regular expression too, while the automaton checker does not.
Notes
- The reason why we first determine whether or not to use the fuzzing on a sum of the numbers of quantifiers in the regular expression is to perform ReDoS detection from a practical point of view. For example,
/^(a|a){32}$/is considered safe in theory because it has only a finite number of ambiguities, but in practice, it may try matching processes and is obviously vulnerable.